A 6502 that takes 4 callers simultaneously
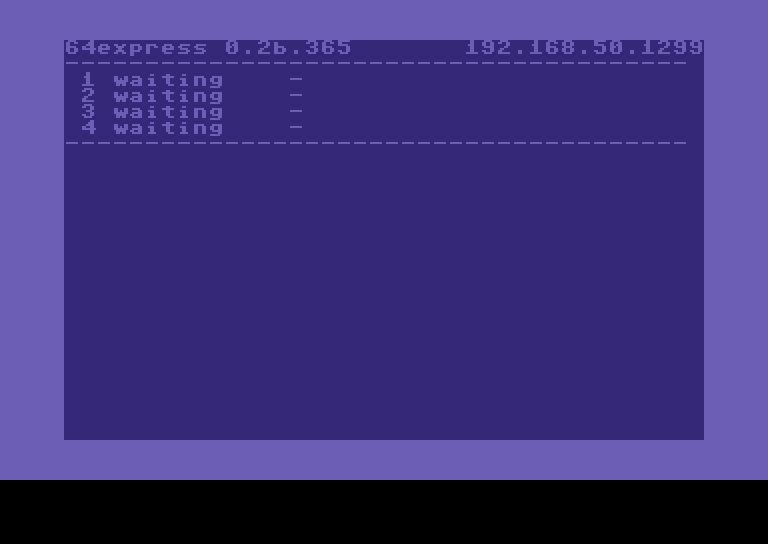
I wanted an Ami-Express style BBS on the c64. Not a single-line board like every C64 BBS i have ever seen, but one machine serving several callers at the same time. As far as i can tell nobody ever did that on a 6502, so with Claude by my side, how hard could it be?
What i wanted
Ami-Express (/X) is the Amiga BBS that a lot of the warez scene
ran on, written by Michael Thomas and developed between 1992 and 1995.
Conferences, ratios, file areas, the lot. Nobody ever ported it to the C64, and
the C64's own BBS tradition - C*Base, Image, C-Net - went a different way and
never picked up that model.
The multi-line part would be the real challenge. Multi-line C64 boards did exist, but they were built by putting a whole computer behind each modem and sharing a hard drive between them. Two callers meant two C128s. Nobody, as far as i can find, ever had one 6502 serving two people at once.
So that was the goal: one C64, one program, several callers, none of them waiting for the others.
Being honest about the hardware
Before anyone else says it: this is not a breadbin. It runs on an Ultimate 64 Elite — Gideon Zweijtzer's FPGA C64 — at 48 MHz with a 16 MB REU, and both are hard requirements, not nice-to-haves.
That takes a lot of the traditional pain off the table. I did not write a TCP stack. I never touched a modem, RS-232 or the userport. I never went near the IEC bus, which is bit-banged and cycle-timed and falls apart the moment you accelerate — all the disk access goes through a polled command interface that does not care what speed you run at. The 16 MB REU is thirty-two times the biggest expansion Commodore ever sold.
What none of that gives you is concurrency. The Ultimate will happily run a single-line BBS at 48 MHz. Four callers at once is not something megahertz solves, and that turned out to be the whole job.
First problem: the C64 cannot answer the phone
The obvious design is: C64 listens on a port, callers connect. I wrote a probe to test that before building anything on top of it, which is the one decision in this project i would repeat without changing a thing.
probe-listen, on firmware 3.7 and 3.14d
dead endNET_CMD_TCP_LISTENER_START -> 21,UNKNOWN COMMANDThe listener constants exist in the reference library, but the firmware does not implement them, and no changelog up to 3.14d adds them. So the whole "callers connect to the C64" idea was dead on day one.
The way round it is a broker: a small program on a host machine that owns the public port, and the C64 dials out to it, one connection per node. The broker does the telnet negotiation so the 6502 never has to, and hands each caller to a free node.
Annoying, but it turned out fine. It also means the C64 never has to deal with half-open connections or terminal handshakes, which is work it can do without.
Second problem: nothing is allowed to wait
This is the actual core of it. If any part of the program blocks — waiting for a socket, waiting for a disk, waiting for anything — every other caller stops too. So every node is a state machine, and a tick does one small step for each node that has work, then goes round again.
That rules out most of the C library. No printf, no blocking
reads, nothing that waits. The KERNAL is banked out for good and the eight
kilobytes underneath used for buffers.
Then i measured what the interface actually costs, and the numbers changed the design more than anything else did.
| Operation | Cost | What it meant |
|---|---|---|
| Socket write, 200 bytes | 1.4-1.6 ms | Cheap. Batch everything into one write per node per tick. |
| Socket read, nothing there | 31-39 ms | Brutal. Polling four idle sockets flat out burns most of a second per tick learning nothing. |
| REU transfer | 4.6 MB/s | Basically free. Put everything possible in expansion RAM. |
| DOS file handles | 2 | For the whole board. Nodes queue for them through an arbiter. |
So idle links back off - a quiet node gets polled less and less, up to a few seconds - and busy ones get hammered. That one change took a single caller from around 800 bytes a second to about 11 KB/s, and four callers to 12-16 KB/s between them.
Third problem: the deploy loop was a coin flip
Resetting the C64 does not close the sockets the Ultimate is holding for it. Leak enough of them and the whole TCP/IP stack goes down until you pull the power. Which meant every other deploy came up dead, and i spent a while diagnosing a board that was fine, with a network stack that was not.
The fix is to write the socket numbers somewhere that survives a reset, and
close them on the way back up. I picked the cassette buffer at $033C
because nothing in the BBS uses it.
Nothing in the BBS does.. The KERNAL however does. RAMTAS clears
$0002-$0101 and $0200-$03FF on every single reset, so
my note was being wiped by the exact event it existed to survive. It had never
once been read back.
Six deploys in a row, before and after
measurednote at $033C: deploy 1: OK deploy 2: FAIL deploy 3: FAIL deploy 4: FAIL deploy 5: FAIL deploy 6: FAIL note at $07E8 (sprite pointers - below the program, past the end of the screen clear, outside everything RAMTAS touches): deploy 1-6: all OK
Same test, same board, one address apart. This is the fix that made everything after it possible, because up to that point half my measurements were of a machine that was already broken.
Fourth problem: reading a directory
File areas need a listing, so i needed to read a directory off the USB stick.
There is a READ_DIR command and no documentation i could find on how
its replies actually work, so i wrote a probe that dumped raw bytes to a caller
and looked at what came back.
Turns out the status register's state field has four values, not two. The two that are neither idle nor busy mean "there is more of this reply" — and you get the next chunk by acknowledging the last one. A whole directory comes back that way, one entry per chunk, and the initial open carries none of it.
Both ways of getting that wrong are completely silent:
- Command per entryThe second command lands inside the first reply and restarts it, so the first file gets listed over and over. No error.
- Ignore a chunkThe interface never returns to idle, so every command after it fails. The board keeps answering ping while being unable to do anything. No error.
An entry, for the record, is one attribute byte and then the name in ASCII. No size — that is a separate query per file, which is why a listing costs what it does.
The one that ate a day
With listings working on a small area, i pointed it at
/usb0/games, which has 205 files in it. The board died. Not
crashed — it kept answering ping, the console kept redrawing, the scheduler kept
running. It just stopped being able to touch the network, so all four nodes went
quiet and the broker dropped them.
I spent hours on the wrong things: the file count, the long filenames, the memory layout, all of which looked plausible and none of which were it. The problem is that from the outside a board that answers ping but does nothing looks exactly like a crash, and i kept treating it as one.
What finally worked was giving up on inference. A wedged board draws nothing and sends nothing, so anything that reports has to be a bare memory write with no machinery behind it — one byte, straight into screen memory, read off the glass with my own eyes. Due to memory constraints, the more fuctions added the less remaining memory existed to print debug information back.
One line of debugging that did what a day of thinking didn't
verified#define TRACE(d) (*(unsigned char *)0x0427 = (unsigned char)(d))
1 entered 2 interface idle 3 command pushed 4 command finished
5 reply read 6 status read 7 acknowledged 9 returning
it stopped between 1 and 2. every single time.Between "entered" and "interface is idle" means it never got to send the command at all — it was waiting for an interface that was never coming back.
Changing directory into a 205-file area takes longer than my timeout allowed. So the code gave up on it — and walked away while the Ultimate was still working on it. The interface never went back to idle, and every command after that timed out too.
The fix is one line, really: a timeout has to cancel the thing it gave up on. There is an abort bit for exactly this. Use it, and the command fails properly instead of poisoning everything behind it.
A few more that were my own fault
My name came out wrong
The board marks a sysop with an @ in front of their handle. Mine
is xecaz. It showed up in the who-list as az.
@ is the escape character for MCI codes, and @X
specifically starts a hex escape — so @x opened an escape,
ec got eaten as its two hex digits, and az is what was
left. It only breaks for handles starting with x. Of course it
does.
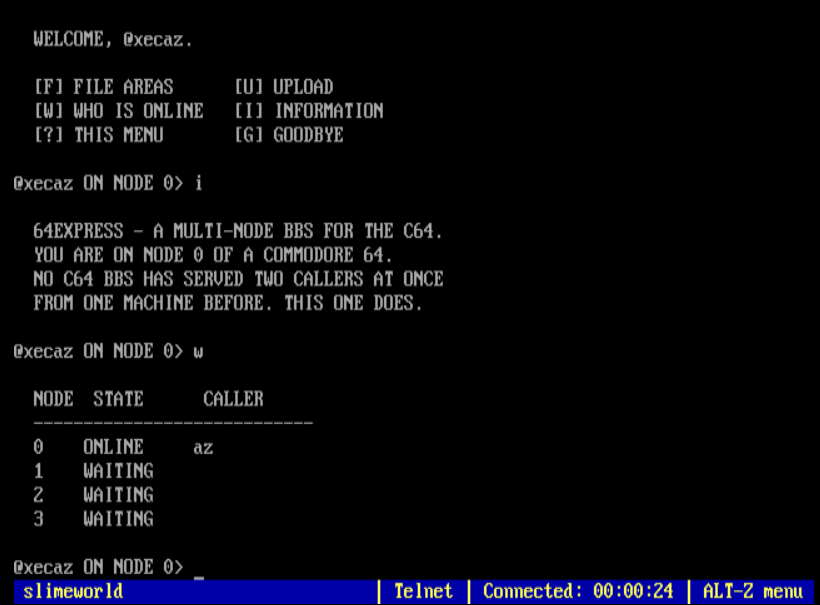
@xecaz ON NODE 0> and the list below
says az. Same name, two code paths — the prompt goes through the
substitution layer where the value gets inserted and not re-parsed, the
who-list prints it as plain text where it does.Fix is not to pick a different marker. The layer already treats
@@ as a literal @ — anything that is not the board's own
text (handles, filenames, descriptions off the stick) just has to go out escaped.
Otherwise a caller can mangle the board's output by choosing their name, which is
a fun thing to leave lying around.
Variables on top of the video chip
The memory config reserved the C stack from BSS, but not from the program itself, and worked out the BSS size by subtraction. Once the program grew past the stack, that subtraction wrapped round to a huge unsigned number, so nothing overflowed and nothing got reported. BSS got laid across the stack and, at 48 KB, across the VIC-II registers.
Variables living on the video chip's control registers. The symptom was a screen full of garbage and then black, and an evening spent bisecting code that was completely fine. The config now stops the program below the stack so the linker complains instead.
The handle that got taken away mid-job
There are two file handles for the whole board, so an arbiter hands them out and takes them back off any node that has held one for more than ten seconds, on the assumption that node has died.
Reading a 205-entry directory takes longer than ten seconds. Nothing renewed the lease while it read, so the handle got reclaimed halfway through and the first file it tried to size found it gone: one line of listing, then "listing interrupted". A 40-file area was quick enough to get away with it, which is exactly why every small test i ran passed and taught me nothing.
What it does now
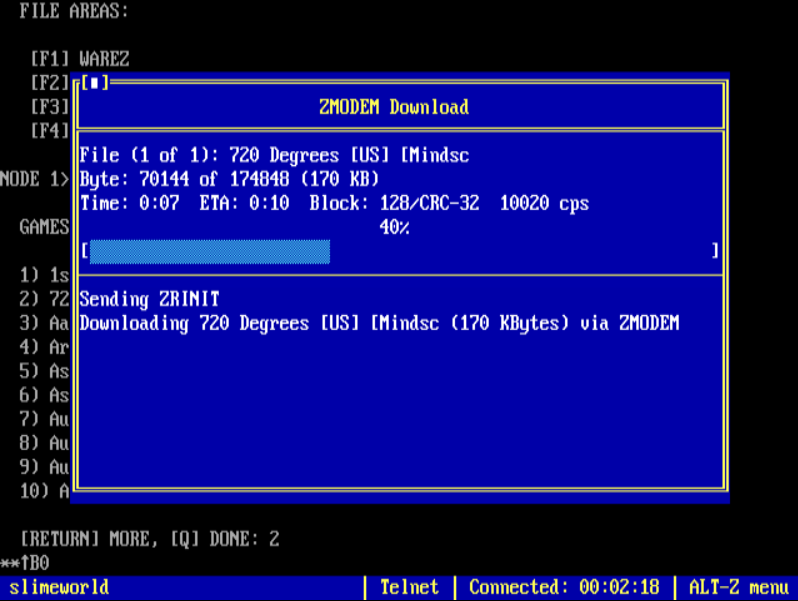
Callers log in against a user list on the stick. There are four file areas — warez, games, demos, and an uploads area only the sysop can see, so nothing a stranger sends gets offered to the next caller until someone has looked at it. Moving a file between the two directories is how you approve it.
Listings show name, size and a description out of a files.bbs,
ten at a time. Every entry is numbered, and typing the number sends you that
file: it gets pulled off the stick into expansion RAM by DMA, without the bytes
going through the CPU at all, and Zmodem streams it out from there while the
other three nodes carry on.
It sits at 47 KB of code against about 51 KB of usable memory, with the RAM under the KERNAL full, so the next feature has to be paid for by deleting something. The last stretch of work was all removal.
366 builds and somewhere around ninety hangs to get here. Most of that was not clever debugging, it was learning to stop guessing: power-cycle before measuring anything, change one thing per deploy, and build something that lets the board tell you where it stopped instead of working it out from silence.
And i still have not found another multi-node BBS running as one 6502 program, on any 6502 machine. That is a "could not find" rather than a "does not exist", so if you know of one i would genuinely like to read about it.
Thanks
To Gideon Zweijtzer for the Ultimate 64 Elite, which is what makes any of this practical — not least being able to push a build straight into C64 memory over the network 366 times without getting out of the chair.
64express